DeepInfra raises $107M Series B to scale the inference cloud — read the announcement
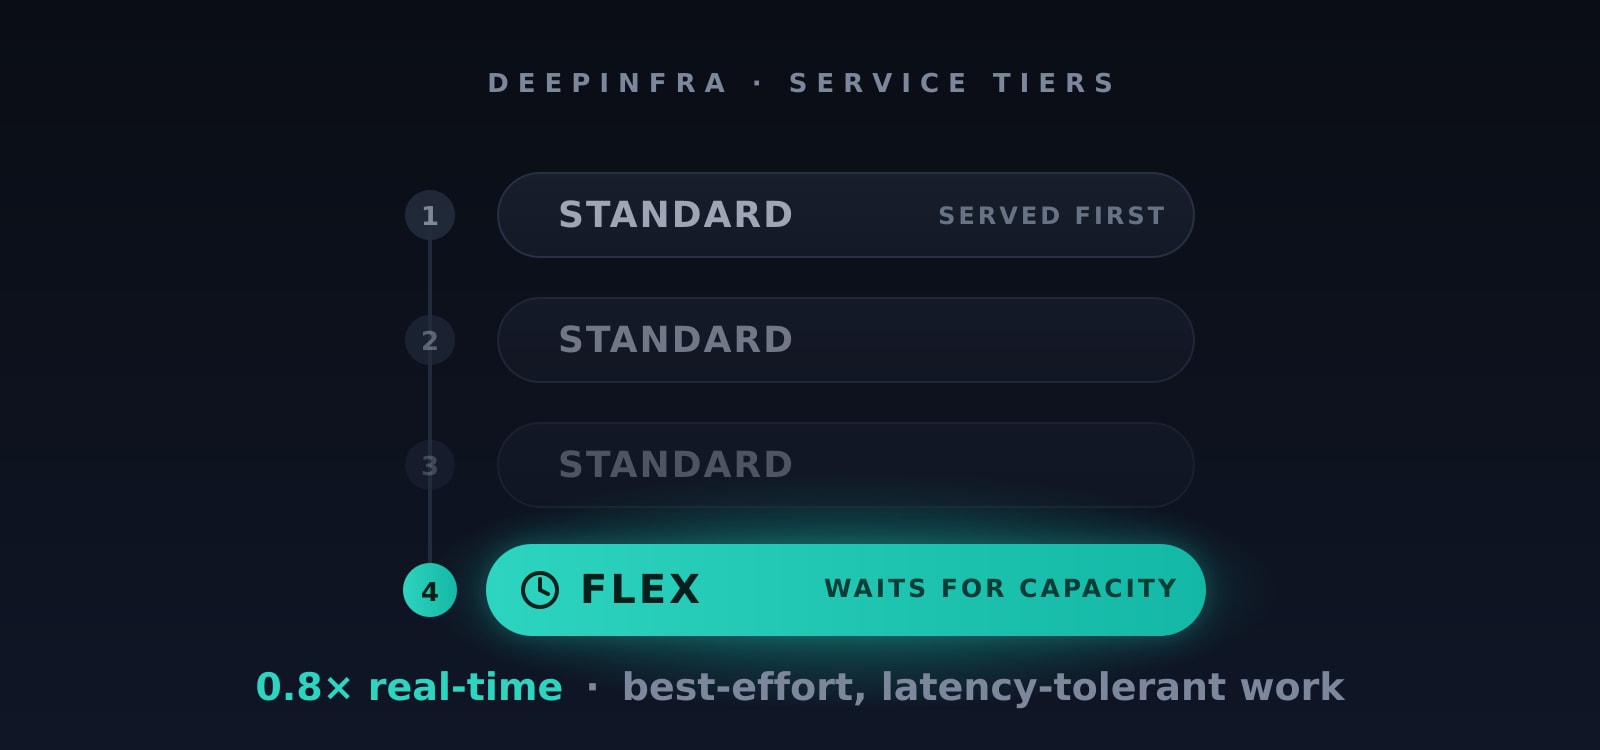
Not every request needs an answer this second. Evaluations, data enrichment, offline pipelines, and other asynchronous jobs care far more about cost than latency. The new Flex service tier runs that work at 0.8× the real-time price — 20% off — in exchange for slower, best-effort scheduling. It's a single OpenAI-compatible field on the request: no separate endpoint, no new API to learn — and it's still a plain synchronous request, not an offline batch job. It mirrors OpenAI's own service_tier: "flex" — the same field with the same intent — so if you already send flex requests to OpenAI, moving that latency-tolerant work here is a one-line change.
Why Flex?
Real-time pricing pays for capacity that's ready the instant you call. If your workload can tolerate waiting, you shouldn't have to pay for that readiness. Flex is built for the jobs where throughput and cost matter more than time-to-first-token:
- Model evaluations and benchmarks — large batches you kick off and collect later.
- Data enrichment and labeling — classifying, extracting, or summarizing across big datasets.
- Asynchronous and non-production workloads — anything queued, retried, or run overnight.
You opt in per request by setting service_tier to "flex". Leave it off and your request runs at the standard real-time tier and price, exactly as it does today — Flex is purely additive.
How It Works
One field. Add "service_tier": "flex" to any chat or completions request. Flex requests are best-effort:
- Cheaper — billed at 0.8× the model's standard per-token price.
- Patient — when a model is busy, a flex request waits up to 10 minutes for available capacity, then either runs or is rejected with an HTTP 429. Use it for work you can retry, not interactive traffic.
- Only billed when served — if a flex request is rejected (a 429 after the wait), you're not charged for it at all. You pay only for requests the model actually handles.
Flex is still a synchronous request. Unlike an offline batch job, your API call behaves like any normal request — it blocks until the model responds (or the wait window expires) and returns the completion inline. Same request, same response shape; only the scheduling and price change.
When a model has spare capacity, flex requests are served right away. The trade-off only shows up under load — flex yields to real-time traffic instead of competing with it.
Supported Endpoints
/v1/chat/completions/v1/completions
Everything works through the standard OpenAI-compatible API you're already using.
Pricing
Flex is billed at 0.8× the corresponding real-time price — a 20% discount, applied automatically, with no extra configuration.
The important part: if a flex request isn't handled, it isn't billed. A request that waits out the window without capacity and returns a 429 costs you nothing — you're only charged for requests the model actually serves. (Send flex to a model that doesn't support the tier and it's served at the standard tier and price instead.)
Supportability Today
Flex is rolling out across our catalog. You don't have to guess which models qualify: every model that supports flex carries a Flex tag on its model page, so you can see at a glance whether a model honors the tier before you send a request.
And you can always confirm it programmatically: send a request with service_tier="flex" and check the echoed service_tier on the response. If it comes back "flex", you're getting the discount; if it comes back "default", the model isn't flex-enabled yet and you were charged the standard price.
Get Started
Using the OpenAI Python client — just add service_tier="flex" and read it back off the response:
from openai import OpenAI
client = OpenAI(
api_key="$DEEPINFRA_TOKEN",
base_url="https://api.deepinfra.com/v1/openai",
)
resp = client.chat.completions.create(
model="meta-llama/Meta-Llama-3.1-8B-Instruct",
messages=[{"role": "user", "content": "Classify this review as positive or negative: ..."}],
service_tier="flex",
)
print(resp.choices[0].message.content)
print("served as:", resp.service_tier) # "flex" when the discount was applied
Or with curl — service_tier is just another field in the JSON body:
curl https://api.deepinfra.com/v1/openai/chat/completions \
-H "Authorization: Bearer $DEEPINFRA_TOKEN" \
-H "Content-Type: application/json" \
-d '{
"model": "meta-llama/Meta-Llama-3.1-8B-Instruct",
"messages": [{"role": "user", "content": "Classify this review as positive or negative: ..."}],
"service_tier": "flex"
}'
The service_tier field on the response tells you which tier actually served the request.
Trade latency for savings
See the Service Tier documentation for the full reference, and start moving your latency-tolerant work to Flex.
 Build a Streaming Chat Backend in 10 Minutes<p>When large language models move from demos into real systems, expectations change. The goal is no longer to produce clever text, but to deliver predictable latency, responsive behavior, and reliable infrastructure characteristics. In chat-based systems, especially, how fast a response starts often matters more than how fast it finishes. This is where token streaming becomes […]</p>
 GLM-5.3-Flash Documentation & Integration Guide<p>GLM-5.3-Flash is a frontier-class, natively multimodal model developed by Z.ai and hosted on DeepInfra. It uses a Mixture-of-Experts (MoE) architecture with 320 billion total parameters, of which only 18 billion are active during inference. The model is built for complex, long-horizon tasks — advanced software engineering, agentic workflows, and multimodal reasoning — with a context […]</p>
 Best Open-Source Multimodal AI Models for Production (2026)<p>Open-source multimodal models have a benchmark problem. Every new release comes with DocVQA and MMMU scores, but those numbers rarely reflect how a model performs on a real workload. A model can lead the leaderboard and still struggle with a scanned invoice, a noisy image, or a multi-step agent workflow. Real-world data is far less […]</p>


© 2026 DeepInfra. All rights reserved.