DeepInfra raises $107M Series B to scale the inference cloud — read the announcement
 Latest article
MiMo-V2.6-Pro is a flagship sparse Mixture-of-Experts (MoE) model built for omnimodal intelligence and autonomous agentic workflows. It has 1.02 trillion total parameters, with 42 billion activated during inference, and is natively built to process text, image, video, and audio within a single, unified architecture. With a 1,048,576-token (1M) context window and optimization via large-scale mixed […]
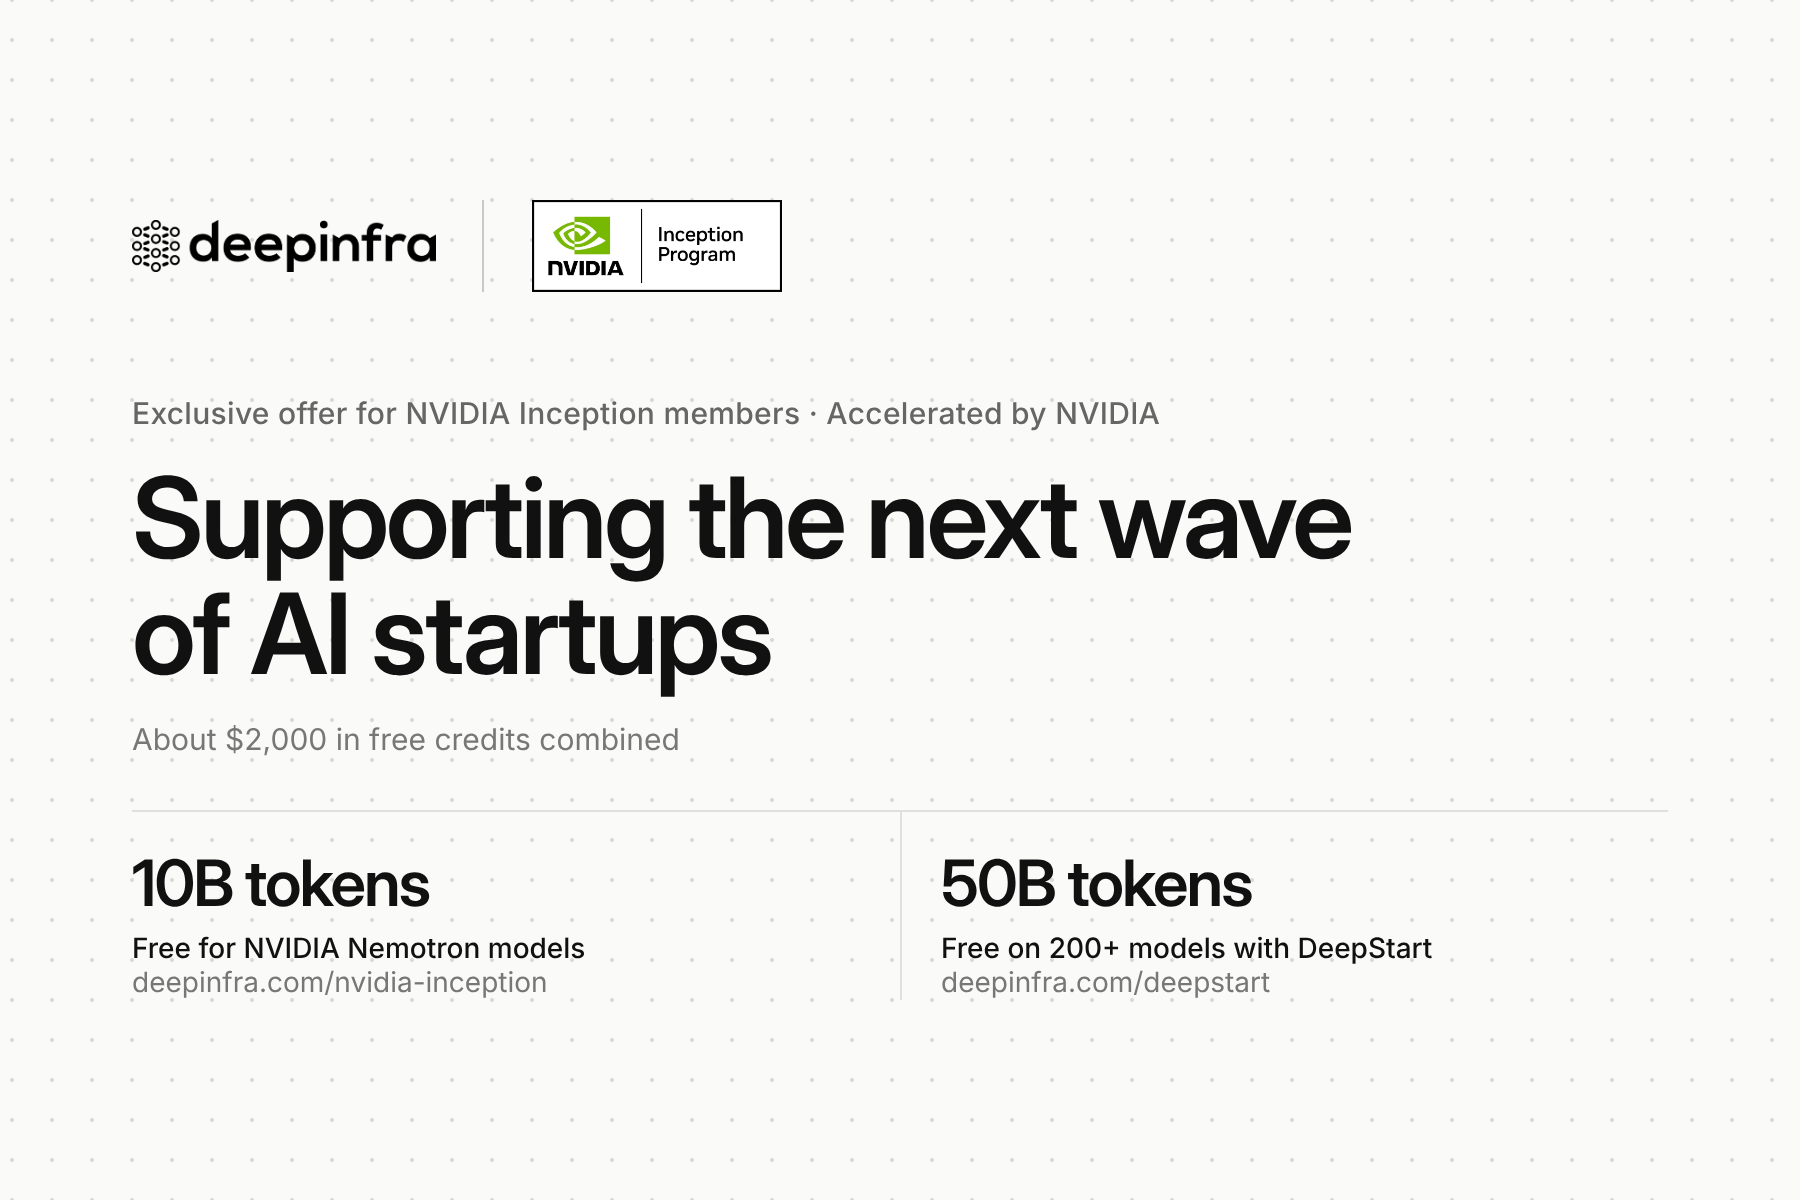 Published on 2026.11.04 by Aray SultanbekovaSupporting the Next Wave of AI Startups with the NVIDIA Inception Program
NVIDIA Inception members get 10 billion free tokens for NVIDIA Nemotron models on DeepInfra, and DeepStart now offers 50 billion free tokens on any of our 200+ models.
 Published on 2026.11.03 by DeepInfraMiMo-V2.6-Pro Guide: Performance, Pricing & Providers
API Review Summary (October 2026) Attribute Value Developer Xiaomi Release Date September 21, 2026 Model Type Reasoning model (open weights) Artificial Analysis Intelligence Index 30 — ranks #3 of 21 models in AA’s “Large” (>150B parameter) class, where the class median is 23 Speed 53.4 output tokens/sec (class median: 73.9 t/s) Latency (TTFT) 3.16s (class […]
 Published on 2026.11.02 by DeepInfraMiMo-V2.6-Pro Pricing Guide: Developer Cost Breakdown
MiMo-V2.6-Pro is the kind of model that gets a pricing guide worth reading: it combines open weights, a 1M-token context window, and pricing that undercuts the typical large open-weight reasoning model. At listed rates of $0.435 per million input tokens and $0.87 per million output tokens, it comes in below the median pricing Artificial Analysis […]
 Published on 2026.11.01 by DeepInfraMiMo-V2.6-Pro Is Now Available on DeepInfra
From 19.0 to 71.9 on DeepSWE — that’s the jump Xiaomi reports between MiMo-V2.5-Pro and MiMo-V2.6-Pro, its new flagship, on real-world software engineering tasks. That puts it, on Xiaomi’s own published figures, alongside Claude Opus 5 (74.0) and GPT-5.6 Sol (73.0) on a benchmark designed to test repository-level coding rather than toy problems. Built by […]
 Published on 2026.10.31 by NiklasWhy Open Models Get Faster Weeks After Launch
Qwen3.8-Flash-Next was released on August 26, 2026. The same day, SGLang announced day-0 support, built with the Qwen, NVIDIA and AMD teams, and shipped a dedicated container image. vLLM served the model from its own dedicated image while the architecture-support work was still being merged. llama.cpp, the engine most people use to run models on […]
 Published on 2026.10.30 by Stefan FidanovBest Jev Alternatives: Hosted APIs and Open Models (2026)
Jev had competitors before it was even a month old. TypeSafe launched it on September 15, and by the first week of October OpenAI had announced a Decisions API, Cloudflare and AWS had shipped open-weight decision models, and GitHub had a shelf of open-source Jev alternatives: Laya, OpenJev, Kev, AnyJev. We ran Jev and the […]


© 2026 DeepInfra. All rights reserved.