DeepInfra raises $107M Series B to scale the inference cloud — read the announcement
NVIDIA Nemotron 3.5 Embed and Rerank, part of the NVIDIA Nemotron Retriever collection, are available on DeepInfra from Day 0. Starting today, you can access Embed 1B, Embed 8B, and Rerank 8B through the DeepInfra API with no deployment setup and pay-per-token pricing.
Enterprise agents are only as good as the information they can retrieve. A support agent needs the specific clause from a policy PDF. A finance agent needs the number contained in a chart, rather than the surrounding text.
Traditional text-only retrieval can miss critical information embedded in tables, charts, and complex document layouts. Nemotron 3.5 Embed helps retrieve information across text and visual content, while Rerank prioritizes the most relevant results for downstream reasoning.
Together, they help developers build retrieval pipelines that provide agents with stronger evidence while using their context and inference budgets more efficiently.
What’s new in Nemotron 3.5 Embed and Rerank?
Embed and Rerank are part of NVIDIA Nemotron Retriever, a collection of open, leaderboard-winning models for building retrieval systems for agents, alongside Nemotron 3.5 Parse for turning complex documents into structured, agent-ready content.
Multimodal embeddings. Nemotron 3.5 Embed creates unified representations across text, tables, charts, images, diagrams, and document pages, so agents can retrieve information even when the answer is expressed visually. It comes in two sizes: 1B for efficiency at scale and 8B for quality-focused retrieval, particularly in agentic workflows.
Reranking built for agents. Nemotron 3.5 Rerank 8B scores retrieved passages against an agent’s question, then prioritizes the most relevant evidence for the reasoning model. It supports agents that retrieve iteratively and compare evidence across multiple sources.
Better retrieval quality, more efficient agent workflows. NVIDIA Nemotron 3.5 Embed 8B leads the ViDoRe v3.1 leaderboard among dense retrieval models, while adding Nemotron 3.5 Rerank reduces agent inference costs by up to 14% in NVIDIA evaluations.
Open and customizable. The weights are open, and NVIDIA publishes NeMo post-training recipes for adapting retrieval to your own terminology, data, and relevance criteria.
What you can build
- Agentic RAG over enterprise documents: Retrieve relevant information from PDFs, presentations, scanned pages, tables, charts, and diagrams—not just extracted text.
- Multi-step research agents: Support query rewriting, iterative retrieval, and evidence comparison across multiple resources.
- Agent memory and code retrieval: Retrieve relevant context from stored interactions, technical documentation, and code repositories to support long-running workflows and coding agents.
Getting started on DeepInfra
Get an API key from the DeepInfra dashboard and set it as DEEPINFRA_TOKEN. The example below embeds a support question and four passages with Embed 1B, keeps the three closest, and reranks them with Rerank 8B. Set input_type to "query" for questions and "passage" for the content you search over.
import os
import numpy as np
import requests
from openai import OpenAI
TOKEN = os.environ["DEEPINFRA_TOKEN"]
EMBED = "nvidia/Nemotron-3.5-Embed-1B-BF16"
RERANK = "nvidia/Nemotron-3.5-Rerank-8B-BF16"
client = OpenAI(
api_key=TOKEN,
base_url="https://api.deepinfra.com/v1/openai",
)
query = "What is the refund window for annual plans?"
docs = [
"Monthly plans can be cancelled at any time from the billing page.",
"Annual plans can be refunded in full within 30 days of purchase.",
"Enterprise contracts follow the terms in the signed order form.",
"Invoices are emailed on the first business day of each month.",
]
# 1. Retrieve: embed the query and documents, keep the closest matches
q = client.embeddings.create(
model=EMBED, input=[query], extra_body={"input_type": "query"}
)
d = client.embeddings.create(
model=EMBED, input=docs, extra_body={"input_type": "passage"}
)
q_vec = np.array(q.data[0].embedding)
d_vecs = np.array([e.embedding for e in d.data])
similarity = d_vecs @ q_vec # vectors are L2-normalized
candidates = [docs[i] for i in np.argsort(-similarity)[:3]]
# 2. Rerank: score each candidate against the query
resp = requests.post(
f"https://api.deepinfra.com/v1/inference/{RERANK}",
headers={"Authorization": f"Bearer {TOKEN}"},
json={"queries": [query] * len(candidates), "documents": candidates},
)
for score, doc in sorted(zip(resp.json()["scores"], candidates), reverse=True):
print(f"{score:.3f} {doc}")
Output:
-1.112 Annual plans can be refunded in full within 30 days of purchase.
-2.912 Monthly plans can be cancelled at any time from the billing page.
-3.290 Invoices are emailed on the first business day of each month.
The passage that answers the question comes out on top. Rerank returns raw relevance scores, so negative values are expected.
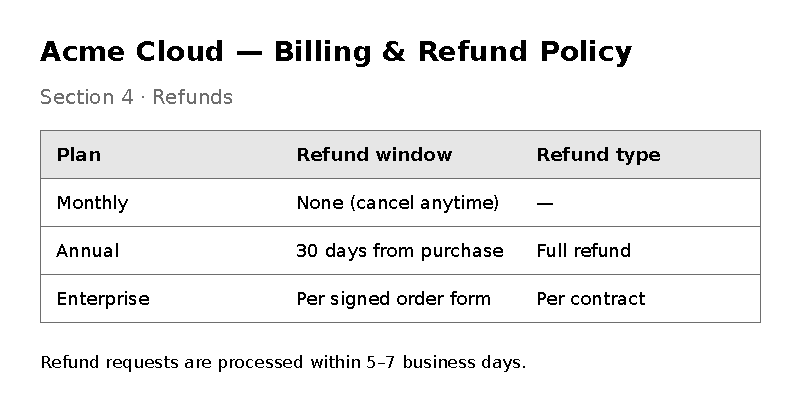
Tip: search page images, too. Embed also accepts images, so a screenshot of a policy table can be retrieved by a plain-language question:
import base64
with open("refund_policy_page.png", "rb") as f:
page_b64 = base64.b64encode(f.read()).decode()
page = client.embeddings.create(
model=EMBED,
input=[[
{"type": "image_url", "image_url": {"url": f"data:image/png;base64,{page_b64}"}},
]],
extra_body={"input_type": "passage"},
)
page_vec = np.array(page.data[0].embedding)
print(f"{page_vec @ q_vec:.3f}")
Output: 0.576 (vs. 0.110 for "How do I reset my password?")
Pricing
DeepInfra offers pay-per-token access to Nemotron 3.5 Embed 1B, Embed 8B, and Rerank 8B. Per 1M input tokens, each with a 32K-token context window:
- Embed 1B is $0.015 for text, $0.035 for image inputs
- Embed 8B is $0.035 for text, $0.070 for image inputs
- Rerank 8B is $0.050
See DeepInfra pricing for current rates.
Get started with Nemotron Retriever on DeepInfra
Build retrieval pipelines that search across text and visual content, rerank candidate results, and provide AI agents with more relevant evidence.
Explore the available models:
Get your API key, follow the Python walkthrough, and start building. Questions or feedback? Contact feedback@deepinfra.com.
 Qwen API Pricing Guide 2026: Max Performance on a Budget<p>If you have been following the AI leaderboards lately, you have likely noticed a name that keeps trading blows with the field’s proprietary leaders: Qwen. Developed by Alibaba Cloud, the Qwen model family has kept expanding at a rapid pace — the current lineup spans Qwen3, Qwen3.5, Qwen3.6, and the flagship Qwen3.8-Max, alongside dedicated coding […]</p>
 DeepSeek V4 Pro Is Now Available on DeepInfra<p>DeepSeek released V4 Pro on April 24, 2026 — a 1.6 trillion-parameter Mixture of Experts model with 49 billion active parameters, a 1-million-token context window, and weights available on Hugging Face under an MIT license. On LiveCodeBench, the V4-Pro-Max reasoning variant scores 93.5 Pass@1, leading every model in the comparison set, including Gemini-3.1-Pro High at […]</p>
 NVIDIA Nemotron 3 Nano 30B API Benchmarks: Latency & Cost<p>About NVIDIA Nemotron 3 Nano 30B A3B NVIDIA Nemotron 3 Nano 30B A3B is a large language model trained from scratch by NVIDIA, designed as a unified model for both reasoning and non-reasoning tasks. It is part of the Nemotron 3 family — NVIDIA’s most efficient family of open models, built for agentic AI applications. […]</p>




© 2026 DeepInfra. All rights reserved.