DeepInfra raises $107M Series B to scale the inference cloud — read the announcement
Starting from langchain v0.0.322 you can make efficient async generation and streaming tokens with deepinfra.
Async generation
The deepinfra wrapper now supports native async calls, so you can expect more performance (no more threads per invocation) from your async pipelines.
from langchain.llms.deepinfra import DeepInfra
async def async_predict():
llm = DeepInfra(model_id="meta-llama/Llama-2-7b-chat-hf")
output = await llm.apredict("What is 2 + 2?")
print(output)
Response streaming
Streaming lets you receive each token of the response as it gets generated. This is indispensable in user-facing applications.
def streaming():
llm = DeepInfra(model_id="meta-llama/Llama-2-7b-chat-hf")
for chunk in llm.stream("[INST] Hello [/INST] "):
print(chunk, end='', flush=True)
print()
You can also use the asynchronous streaming API, natively implemented underneath.
async def async_streaming():
llm = DeepInfra(model_id="meta-llama/Llama-2-7b-chat-hf")
async for chunk in llm.astream("[INST] Hello [/INST] "):
print(chunk, end='', flush=True)
print()
Related articles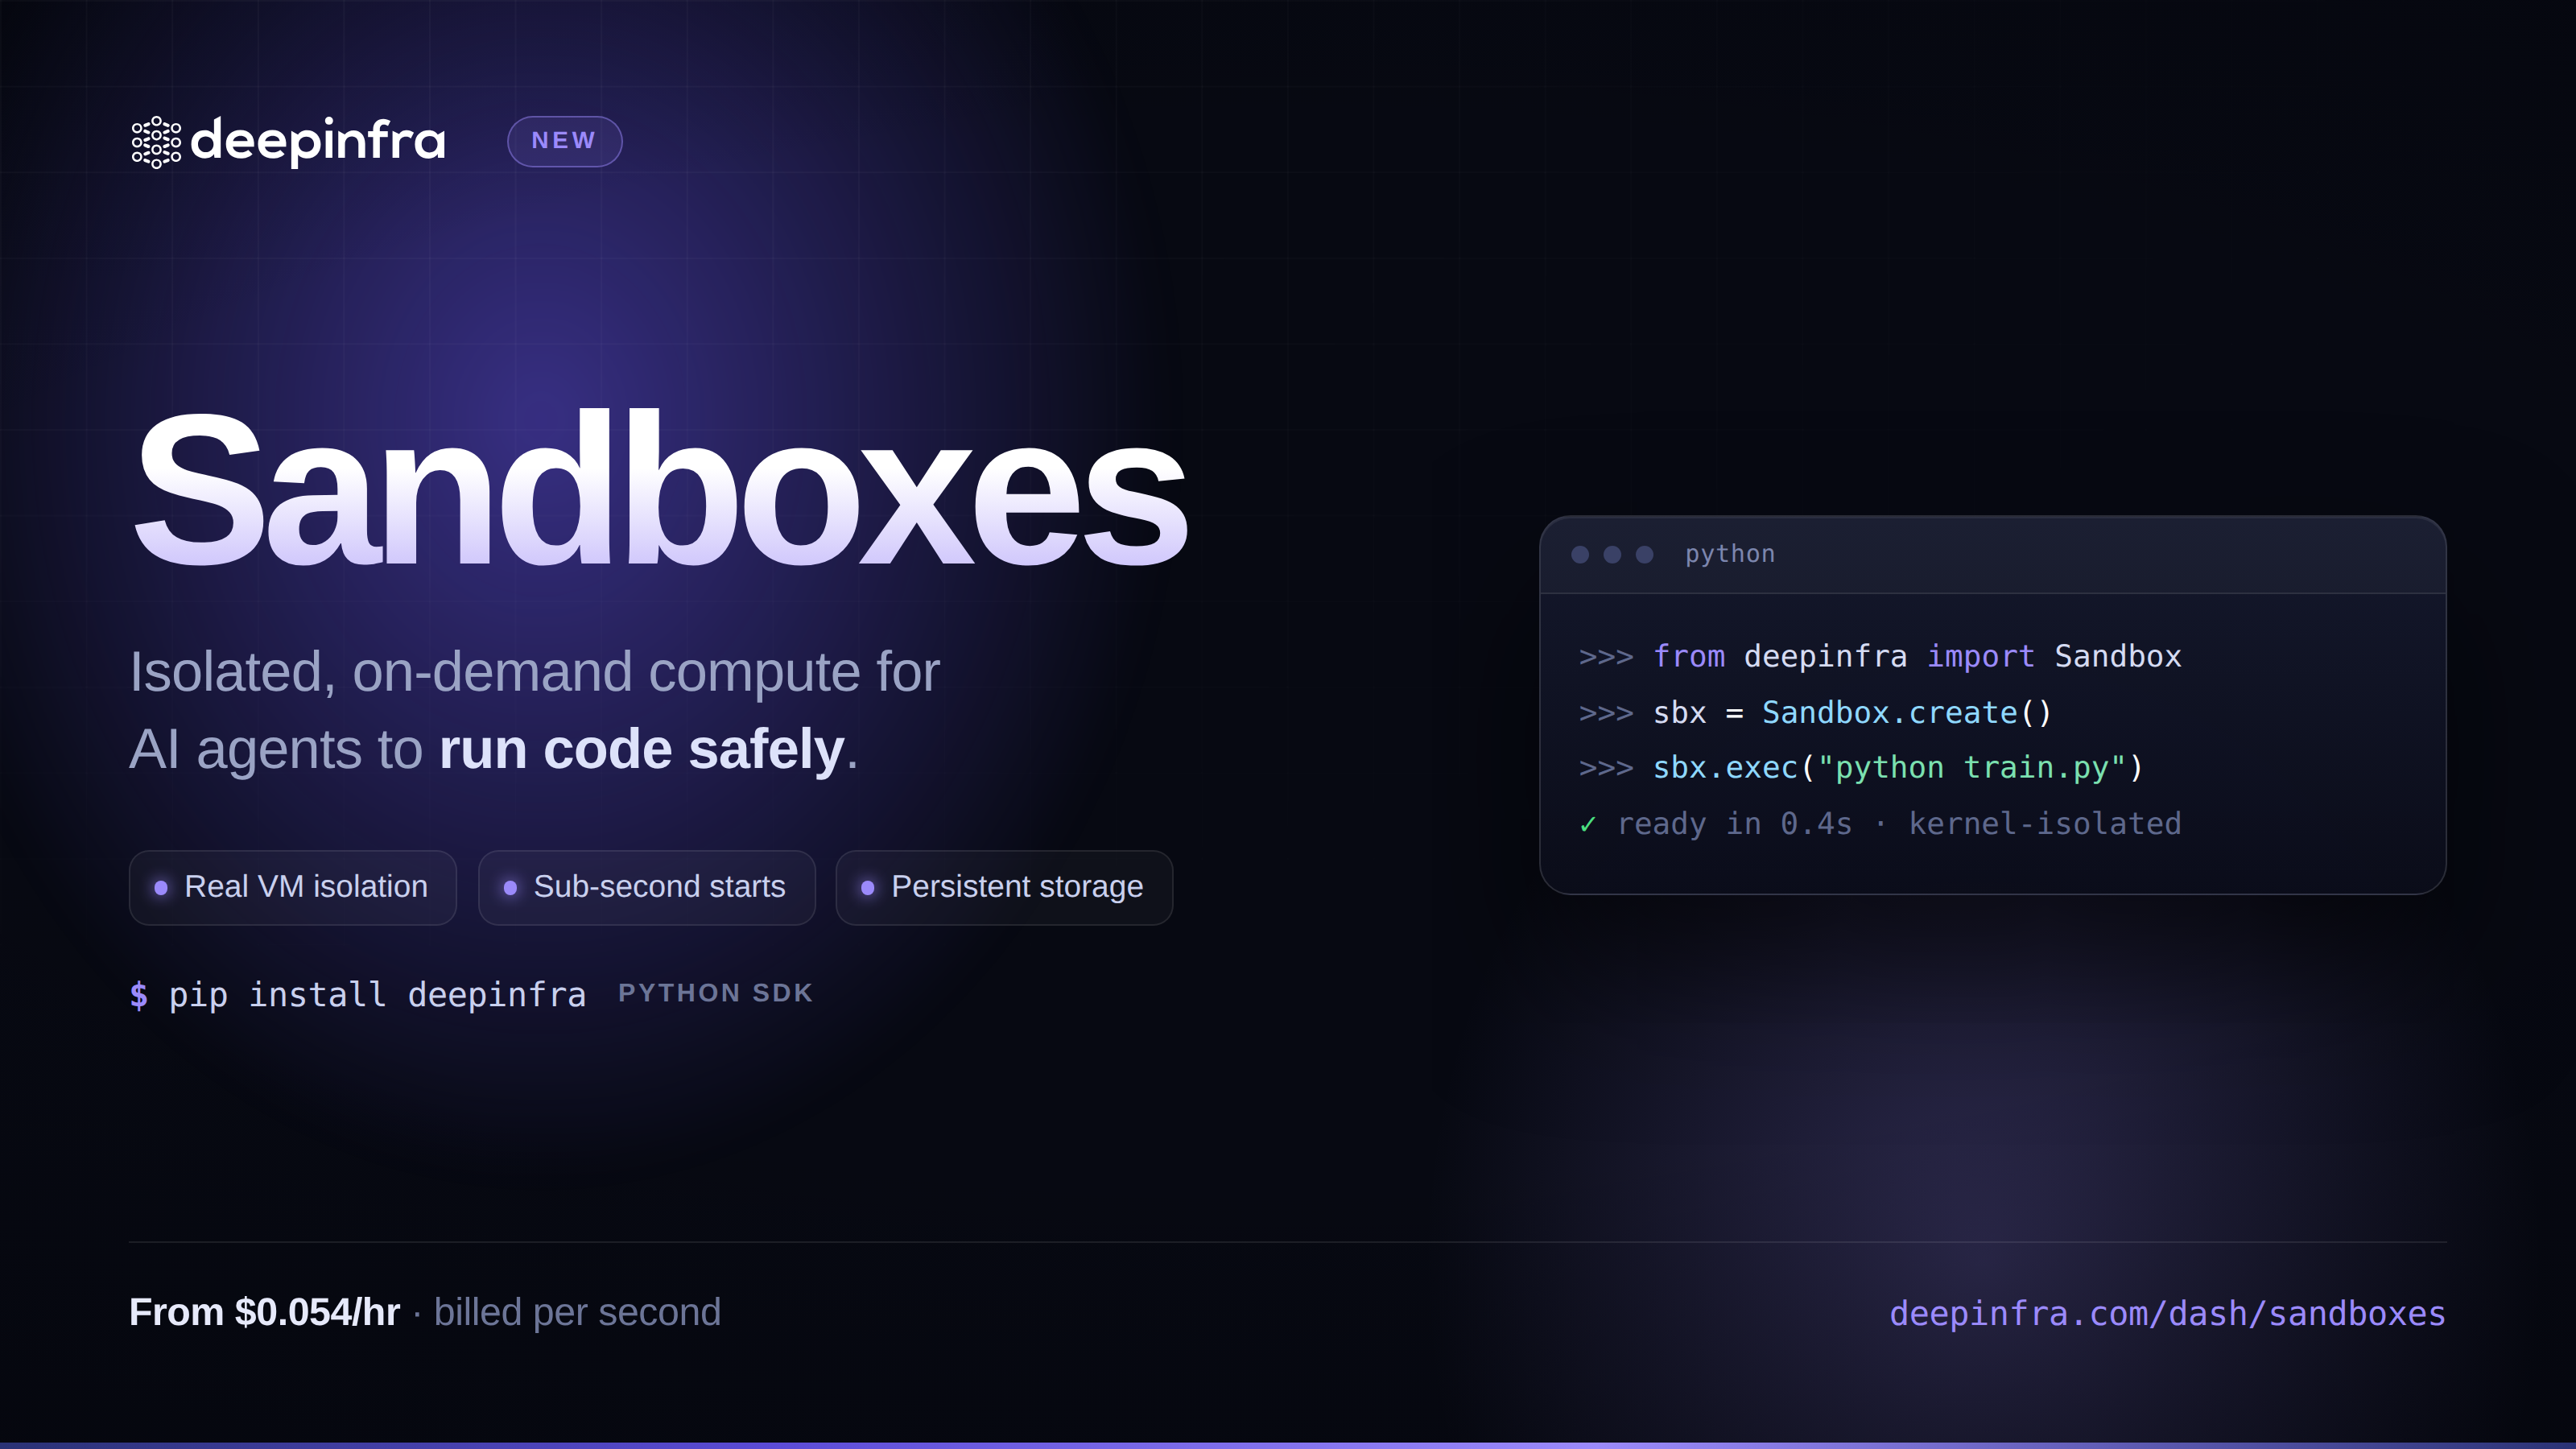 Sandboxes: give your agents a safe place to run codeIsolated Linux microVMs you can spin up with one API call: run bash or Python, move files in and out, pause and resume, tear down when you're done. Built for agents and pipelines that need to execute untrusted code without you having to run the infrastructure yourself.
 Nemotron 3 Nano vs GPT-OSS-20B: Performance, Benchmarks & DeepInfra Results<p>The open-source LLM landscape is becoming increasingly diverse, with models optimized for reasoning, throughput, cost-efficiency, and real-world agentic applications. Two models that stand out in this new generation are NVIDIA’s Nemotron 3 Nano and OpenAI’s GPT-OSS-20B, both of which offer strong performance while remaining openly available and deployable across cloud and edge systems. Although both […]</p>
 Kimi K3 Now Available on DeepInfra<p>Updated November 2026. Update, November 2026: Kimi K3.1 Pro is now available on DeepInfra. It’s post-trained from Kimi K3 with much larger post-training compute, swaps in sparse attention for long context, and costs $1.90 / $9.50 per 1M tokens on DeepInfra, a third below K3 (pricing as of 2026-11-17). Moonshot AI’s Kimi K3 is the […]</p>
Sandboxes: give your agents a safe place to run codeIsolated Linux microVMs you can spin up with one API call: run bash or Python, move files in and out, pause and resume, tear down when you're done. Built for agents and pipelines that need to execute untrusted code without you having to run the infrastructure yourself.Nemotron 3 Nano vs GPT-OSS-20B: Performance, Benchmarks & DeepInfra Results<p>The open-source LLM landscape is becoming increasingly diverse, with models optimized for reasoning, throughput, cost-efficiency, and real-world agentic applications. Two models that stand out in this new generation are NVIDIA’s Nemotron 3 Nano and OpenAI’s GPT-OSS-20B, both of which offer strong performance while remaining openly available and deployable across cloud and edge systems. Although both […]</p>
Kimi K3 Now Available on DeepInfra<p>Updated November 2026. Update, November 2026: Kimi K3.1 Pro is now available on DeepInfra. It’s post-trained from Kimi K3 with much larger post-training compute, swaps in sparse attention for long context, and costs $1.90 / $9.50 per 1M tokens on DeepInfra, a third below K3 (pricing as of 2026-11-17). Moonshot AI’s Kimi K3 is the […]</p>


© 2026 DeepInfra. All rights reserved.