DeepInfra raises $107M Series B to scale the inference cloud — read the announcement
Did you just finetune your favorite model and are wondering where to run it? Well, we have you covered. Simple API and predictable pricing.
Put your model on huggingface
Use a private repo, if you wish, we don't mind. Create a hf access token just for the repo for better security.
Create custom deployment
Via Web
You can use the Web UI to create a new deployment.
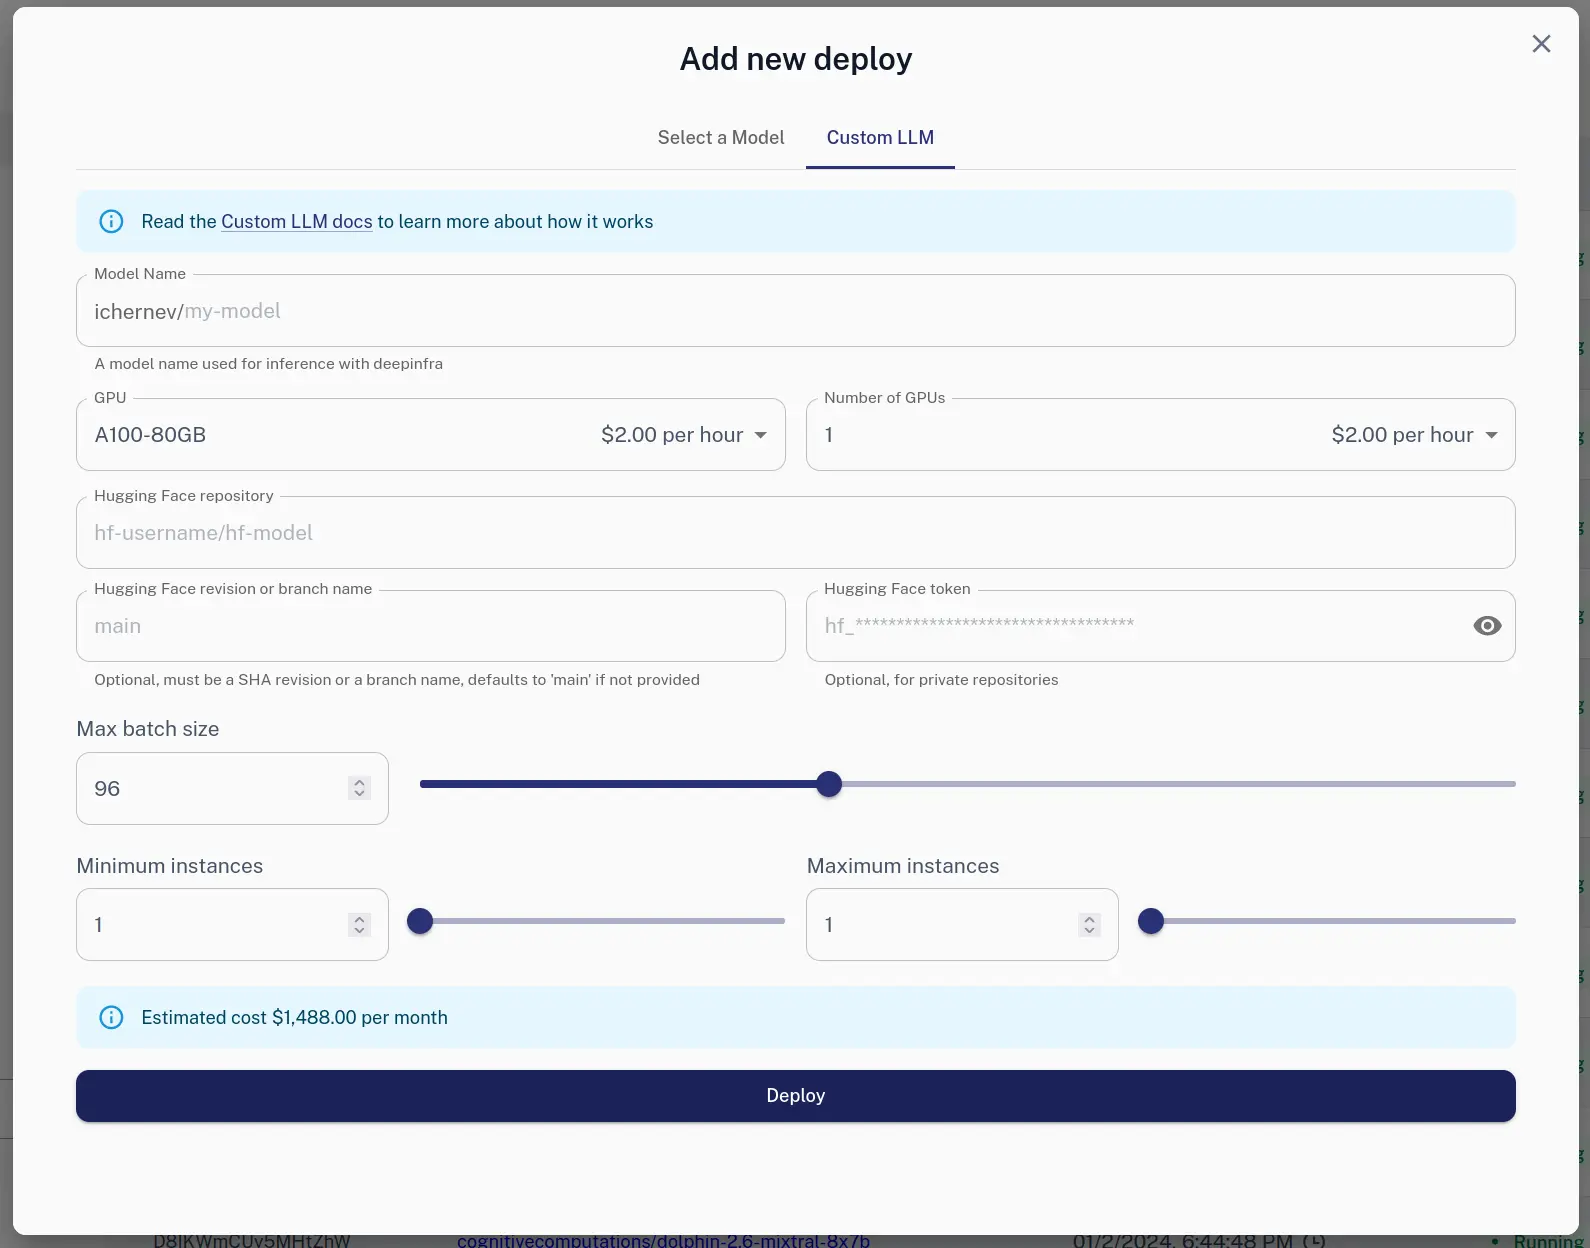
Via HTTP
We also offer HTTP API:
curl -X POST https://api.deepinfra.com/deploy/llm -d '{
"model_name": "test-model",
"gpu": "A100-80GB",
"num_gpus": 2,
"max_batch_size": 64,
"hf": {
"repo": "meta-llama/Llama-2-7b-chat-hf"
},
"settings": {
"min_instances": 1,
"max_instances": 1,
}
}' -H 'Content-Type: application/json' \
-H "Authorization: Bearer YOUR_API_KEY"
Use it
curl -X POST \
-d '{"input": "Hello"}' \
-H 'Content-Type: application/json' \
-H "Authorization: Bearer YOUR_API_KEY" \
'https://api.deepinfra.com/v1/inference/github-username/di-model-name'
For in depth tutorial check Custom LLM Docs.
Related articles Best OpenClaw Alternatives: Hermes Agent, ZeroClaw & NemoClaw<p>OpenClaw has 362,000 GitHub stars and a skill marketplace with over 44,000 community contributions. That kind of adoption doesn’t happen by accident. Still, the same teams running it in production keep running into the same complaint: the model list is fixed. OpenClaw’s guided setup wizard covers OpenAI, Anthropic, Google, DeepSeek, and local Ollama. You can […]</p>
 From Precision to Quantization: A Practical Guide to Faster, Cheaper LLMs<p>Large language models live and die by numbers—literally trillions of them. How finely we store those numbers (their precision) determines how much memory a model needs, how fast it runs, and sometimes how good its answers are. This article walks from the basics to the deep end: we’ll start with how computers even store a […]</p>
 Introducing Wan 3.0 on DeepInfra<p>Wan3.0 is a video generation model from Alibaba’s Wan team that combines text-to-video, image-to-video, reference-based generation, video editing, and video extension in a single model. The media you send with a request selects the workflow, so one model handles every input type. A request can combine a text prompt with up to 20 reference assets, […]</p>
Best OpenClaw Alternatives: Hermes Agent, ZeroClaw & NemoClaw<p>OpenClaw has 362,000 GitHub stars and a skill marketplace with over 44,000 community contributions. That kind of adoption doesn’t happen by accident. Still, the same teams running it in production keep running into the same complaint: the model list is fixed. OpenClaw’s guided setup wizard covers OpenAI, Anthropic, Google, DeepSeek, and local Ollama. You can […]</p>
From Precision to Quantization: A Practical Guide to Faster, Cheaper LLMs<p>Large language models live and die by numbers—literally trillions of them. How finely we store those numbers (their precision) determines how much memory a model needs, how fast it runs, and sometimes how good its answers are. This article walks from the basics to the deep end: we’ll start with how computers even store a […]</p>
Introducing Wan 3.0 on DeepInfra<p>Wan3.0 is a video generation model from Alibaba’s Wan team that combines text-to-video, image-to-video, reference-based generation, video editing, and video extension in a single model. The media you send with a request selects the workflow, so one model handles every input type. A request can combine a text prompt with up to 20 reference assets, […]</p>



© 2026 DeepInfra. All rights reserved.