DeepInfra raises $107M Series B to scale the inference cloud — read the announcement
Getting started
# create a virtual environment
python3 -m venv .venv
# activate environment in current shell
. .venv/bin/activate
# install openai python client
pip install openai
Choose a model
Run OpenAI chat.completion
import openai
stream = True # or False
# Point OpenAI client to our endpoint
openai.api_key = "<YOUR DEEPINFRA API KEY>"
openai.api_base = "https://api.deepinfra.com/v1/openai"
# Your chosen model here
MODEL_DI = "meta-llama/Llama-2-70b-chat-hf"
chat_completion = openai.ChatCompletion.create(
model=MODEL_DI,
messages=[{"role": "user", "content": "Hello world"}],
stream=stream,
max_tokens=100,
# top_p=0.5,
)
if stream:
# print the chat completion
for event in chat_completion:
print(event.choices)
else:
print(chat_completion.choices[0].message.content)
Note that both streaming and batch mode are supported.
Existing OpenAI integration
If you're already using OpenAI chat completion in your project, you need to
change the api_key, api_base and model params:
import openai
# set these before running any completions
openai.api_key = "YOUR DEEPINFRA TOKEN"
openai.api_base = "https://api.deepinfra.com/v1/openai"
openai.ChatCompletion.create(
model="CHOSEN MODEL HERE",
# ...
)
Pricing
Our OpenAI API compatible models are priced on token output (just like OpenAI). Our current price is $1 / 1M tokens.
Docs
Check the docs for more in-depth information and examples openai api.
Related articles Qwen3.5 4B via DeepInfra: Latency, Throughput & Cost<p>About Qwen3.5 4B (Reasoning) Qwen3.5 4B is a compact 4-billion parameter open-weights model released in March 2026 as part of Alibaba Cloud’s Qwen3.5 Small Model Series. It employs an Efficient Hybrid Architecture combining Gated Delta Networks (a form of linear attention) with sparse Mixture-of-Experts, delivering high-throughput inference with minimal latency overhead — a significant architectural […]</p>
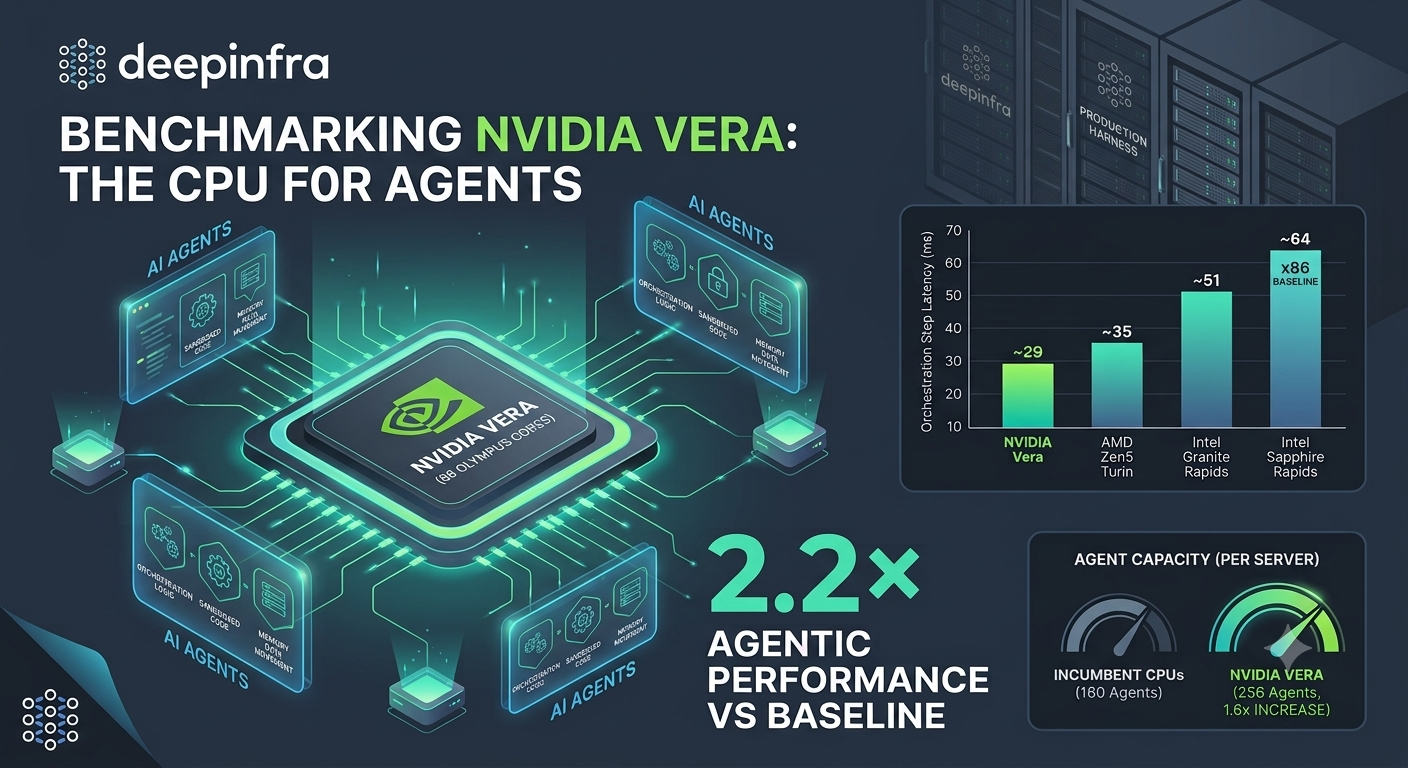 We Benchmarked NVIDIA Vera, the CPU for Agents. Here's What We MeasuredDeepInfra runs AI agents in production, so when NVIDIA built a CPU for agents, we measured it ourselves with our own harness, our own agent, and a methodology we locked before the hardware arrived.
 NVIDIA Nemotron 3.5 Lightning Is Live on DeepInfra: Day-Zero Access to the Fastest Open Model for AgentsNVIDIA Nemotron 3.5 Lightning is available on DeepInfra's serverless API from day zero. It's a 30B hybrid MoE model with 3B active parameters, a 1M-token context window, and up to 4x higher throughput for high-volume agentic workloads.
Qwen3.5 4B via DeepInfra: Latency, Throughput & Cost<p>About Qwen3.5 4B (Reasoning) Qwen3.5 4B is a compact 4-billion parameter open-weights model released in March 2026 as part of Alibaba Cloud’s Qwen3.5 Small Model Series. It employs an Efficient Hybrid Architecture combining Gated Delta Networks (a form of linear attention) with sparse Mixture-of-Experts, delivering high-throughput inference with minimal latency overhead — a significant architectural […]</p>
We Benchmarked NVIDIA Vera, the CPU for Agents. Here's What We MeasuredDeepInfra runs AI agents in production, so when NVIDIA built a CPU for agents, we measured it ourselves with our own harness, our own agent, and a methodology we locked before the hardware arrived.NVIDIA Nemotron 3.5 Lightning Is Live on DeepInfra: Day-Zero Access to the Fastest Open Model for AgentsNVIDIA Nemotron 3.5 Lightning is available on DeepInfra's serverless API from day zero. It's a 30B hybrid MoE model with 3B active parameters, a 1M-token context window, and up to 4x higher throughput for high-volume agentic workloads.


© 2026 DeepInfra. All rights reserved.