DeepInfra raises $107M Series B to scale the inference cloud — read the announcement

With each new model release, we see new benchmark claims and new arguments justifying the value of its tokens. However, when teams compare models for real-world workloads, the sticker price alone hides large per-task differences in the amount of work a model requires to solve a task.
Cheaper tokens do not necessarily translate to lower costs. So, what actually determines the cost of running a model?
In this article, we will explore the hidden costs of token consumption, how reasoning, retries, and task efficiency affect total cost, and discuss how DeepInfra helps manage and optimize these factors.
The Hidden Cost Nobody Puts on the Pricing Page
Per-token pricing does not tell you what a task will actually cost.
A model that costs less per token isn’t necessarily cheaper to run. A million tokens from one model may not produce the same amount of text or complete the same task as another model. This is why the price per token is less useful as a standalone measure of cost.
But token consumption creates a hidden cost difference. A cheaper model can become more expensive if it needs several attempts. A pricier model can be more economical if it gets the task right the first time.
The real cost depends on more than the number printed on a pricing page. It depends on how many tokens a model uses, how efficiently it completes the task, and how often it succeeds. Therefore, two models with similar token prices can have very different real-world costs.
Kimi K3 and DeepSeek V4 Pro: Benchmarking Token Usage
Token consumption can vary significantly between models when evaluated on the same benchmark.
During the Artificial Analysis evaluation, Kimi K3 generated 130 million output tokens. This is more than twice the 63 million median for comparable open-weight models. Kimi K3’s always-on reasoning feature contributes to its unusually high token usage.
Kimi K3 also sits in the mid-to-premium pricing tier. Its output cost is $15 per million tokens, whereas the median for open-weight models is $10 per million tokens. When you add its high token consumption to the cost equation, each benchmark run becomes especially costly.
DeepSeek V4 Pro presents a different side of the same issue. In its Think Max mode, it generated approximately 190 million output tokens. This is more than four times the 47 million-token median for comparable open-weight models. At a rate of $2.60 per million output tokens, this usage would result in roughly $494 in output-token charges, compared to about $122 at the median usage level.
Yet, DeepSeek V4 Pro has a much lower output price than Kimi K3. Even so, its high token consumption increases the overall cost of running it. This only shows why token price alone can be misleading. A model may have a lower price per token but consume far more tokens to complete a task. Therefore, the number of tokens generated changes the economics of running a model.
Why Do Some Models Use So Many More Tokens
Models can use very different numbers of tokens to solve the same task. Several factors contribute to this difference:
Reasoning Depth Affects Token Usage
Reasoning models can use additional tokens to work through a problem before producing the final answer. These reasoning tokens are not visible in the final response, but they still count toward output usage and cost.
Higher reasoning effort can increase token consumption and response latency. A brief visible answer may use more tokens than its displayed text suggests.
Tokenizers Change How Text Is Counted
Token usage also depends on how a model segments text into tokens. A token can represent a character, part of a word, an entire word, or punctuation.
The same text can produce different token counts depending on the model, its encoding, and the language. Factors such as spaces, capitalization, and spelling also determine how text is divided.
Model Size Is Not The Only Factor
Model size alone does not tell you how many tokens a task will consume. Token usage depends on the input, the generated output, reasoning tokens, and the way the model processes the task.
The number of input tokens does not predict how many output tokens a model will generate. Token consumption depends on the workload and the model’s behavior, rather than solely on the model’s size.
When Token Usage Becomes an Inference Problem
Token consumption affects the computational workload required to complete a task. Generating more output tokens requires more computation, but this relationship is not linear. Input length, context, media type, reasoning depth, and the specific use case all impact the amount of computation a task requires.
A model may also use additional tokens for reasoning before producing its final response. Creating a small set of predefined labels typically requires fewer tokens. Generating a complete schema from image-based documents requires the model to analyze much more information. The more a model needs to analyze the input or reason through a task, the more computation the inference process can require.
Output generation also causes latency because output tokens are generated sequentially. Each new token depends on the tokens generated before it, which can cause longer outputs to take more time to produce. Input processing works differently because much of the input can be processed in parallel. This makes output length an important factor in inference latency, especially for workloads that generate long responses or require extensive reasoning.
More demanding workloads may require more compute resources and increase inference costs. As workload complexity varies, teams need ways to control how much computation each request requires. Inference infrastructure can provide these controls through reasoning effort, context caching, and model selection.
These controls can reduce unnecessary computation while preserving the resources needed for more complex tasks. The goal is not simply to generate fewer tokens but to align the amount of computation with the actual requirements of the task.
Where DeepInfra Changes the Inference Economics
Now that we understand that inference economics is not just about selecting the model with the lowest price per token or the cheapest average run. The next question is how to control the factors that determine the actual cost of inference. This cost depends on how much context you send, how much the model reasons, and how efficiently each request is served.
DeepInfra is an AI inference cloud platform that gives teams access to over 200 open-source models, along with private GPU deployments. It provides developers with visibility and control over these factors, helping them to effectively manage the cost and performance of inference tasks.
The following capabilities show how teams can control inference economics:
Prompt Caching Reduces the Cost of Repeated Input
Many workloads repeatedly send the same context with each request. This context might include a long system prompt, a large document, or a fixed set of few-shot examples.
DeepInfra’s prompt caching reuses the key-value (KV) cache when the beginning of a prompt matches a cached prefix. This approach avoids recomputing the cached portion, thereby reducing the time to generate the first token and lowering costs.
When the same prefix appears at the beginning of many requests, those tokens can be served at a significantly lower cost. This makes caching especially useful for workloads that repeatedly send the same system prompts, documents, or other static context.
Prompt caching works automatically on supported models. Teams can get the most benefit by placing stable content at the beginning of the prompt and maintaining an identical prefix across requests.
Request-Level Cost Visibility Shows Actual Spending
DeepInfra includes prompt tokens, completion tokens, total tokens, and estimated costs in its API responses.
This provides teams with a request-level view of their inference usage. They can see whether costs come from large inputs, long outputs, or both. This matters for workloads where context grows over time or where agents make multiple calls to complete a task.
Teams can use this visibility to compare actual request costs across different models and workloads. It also simplifies identifying costly requests and finding opportunities to reduce unnecessary token usage.
Reasoning Controls Let Developers Trade Depth for Cost
DeepInfra’s reasoning_effort parameter controls how much reasoning a model performs. Higher effort means deeper reasoning, more output tokens, and higher latency. Increasing reasoning effort can also increase inference costs.
Developers can set reasoning effort based on the task. You can use higher effort for complex math, logic, and coding problems. Simple Q&A, translation, and summarization tasks can use lower effort or disable reasoning entirely. Cost-sensitive workloads can use none or low to reduce unnecessary reasoning.
Teams can also just choose between reasoning and non-reasoning models depending on the workload.
Live Inference Metrics Show Serving Efficiency
DeepInfra provides live inference metrics including tokens_per_second, time_to_first_token, and requests_per_second. These metrics capture different parts of serving performance. Tokens per second measures generation throughput. Time to first token shows how quickly generation begins. Requests per second shows how much request traffic the deployment is serving.
For dedicated deployments, you also receive metrics such as average time to first token, average time per token, request counts, input and output token counts, total inference time, and error rates.
These metrics add context for token-based costs. Teams can see how much traffic a deployment handles and how efficiently it processes that workload. This is important because inference costs depend not only on the number of tokens per request but also on the number of requests run each day and how efficiently the workload is served.
Final Thoughts
A pricier model that is less chatty can end up cheaper overall, and nobody’s pricing page shows that. The better metric to consider is the cost per successfully completed task, not price per million tokens.
DeepInfra is an inference partner that helps teams optimize cost, latency, throughput, and scalability. It provides developers with the controls and visibility needed to manage inference costs more effectively and design solutions that meet their priorities.
Explore DeepInfra’s models to compare pricing, token usage, and inference performance. Use models that deliver the right balance of cost, reasoning depth, and performance for your workloads.
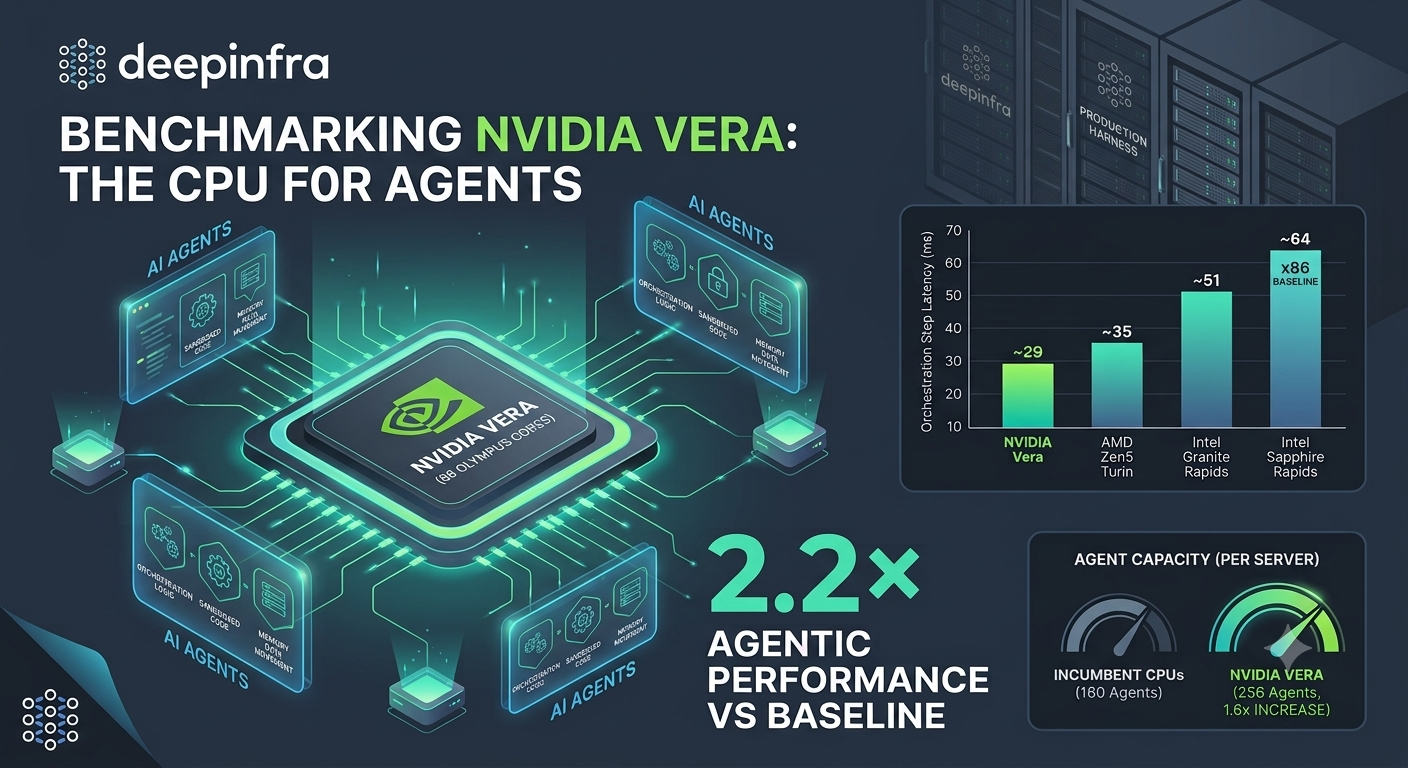 We Benchmarked NVIDIA Vera, the CPU for Agents. Here's What We MeasuredDeepInfra runs AI agents in production, so when NVIDIA built a CPU for agents, we measured it ourselves with our own harness, our own agent, and a methodology we locked before the hardware arrived.
 Kimi K2.6 API Benchmarks: Latency, TPS & Cost Analysis (2026)<p>About Kimi K2.6 Kimi K2.6 is an open-source frontier model from Moonshot AI, released on April 20, 2026. It is a native multimodal agentic model built for long-horizon coding, autonomous execution, and swarm-based task orchestration. The model uses a Mixture-of-Experts (MoE) architecture with 1 trillion total parameters and 32 billion activated parameters per token, using […]</p>
 Best Open Source LLM API Providers in 2026<p>Picking an inference vendor used to be a short conversation. You wanted Llama behind an HTTP endpoint, three companies served it, and their prices sat close enough that the decision came down to whoever had capacity. The market has since split into a dozen serious operators running truly different businesses. The best open source LLM […]</p>


© 2026 DeepInfra. All rights reserved.