DeepInfra raises $107M Series B to scale the inference cloud — read the announcement
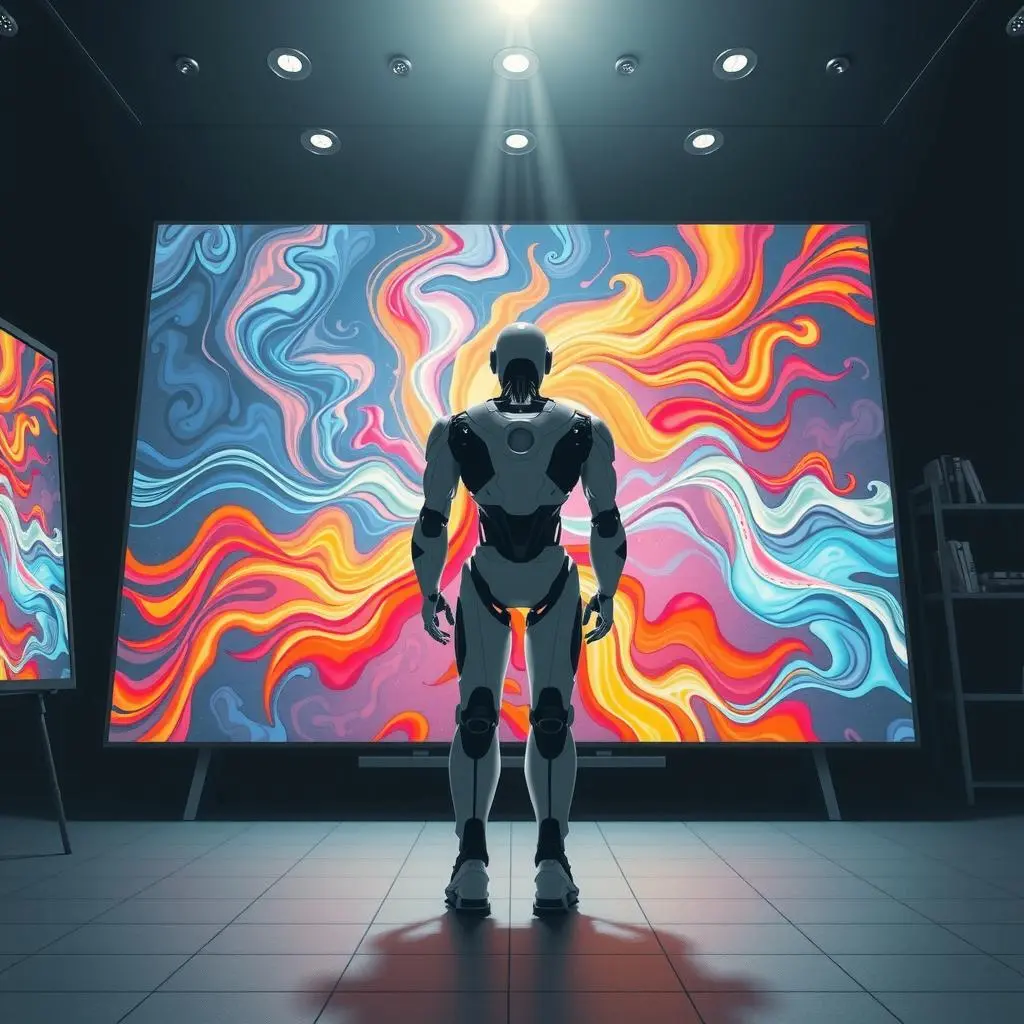
Juggernaut FLUX is live on DeepInfra!
At DeepInfra, we care about one thing above all: making cutting-edge AI models accessible. Today, we're excited to release the most downloaded model to our platform.
Whether you're a visual artist, developer, or building an app that relies on high-fidelity outputs, this is the model series you need.
With over 12 million downloads across platforms like HuggingFace and Civitai, the Juggernaut FLUX Series has earned its place as the most trusted name in photorealistic AI image generation. This series delivers results. From lightning-fast inference speeds to pro-grade detail rendering, these models are for creators who expect more from their tools.
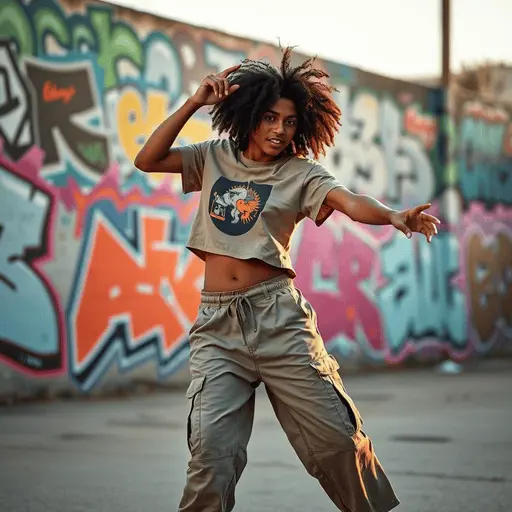
Juggernaut Lightning Flux
Prompt: A Brazilian street dancer with caramel skin and curly hair wearing a cropped graphic tee and loose cargo pants mid-movement in an expressive hip-hop pose, a vibrant graffiti-covered wall behind them. Golden hour lighting.
Num inference steps: 4
Seed: 42
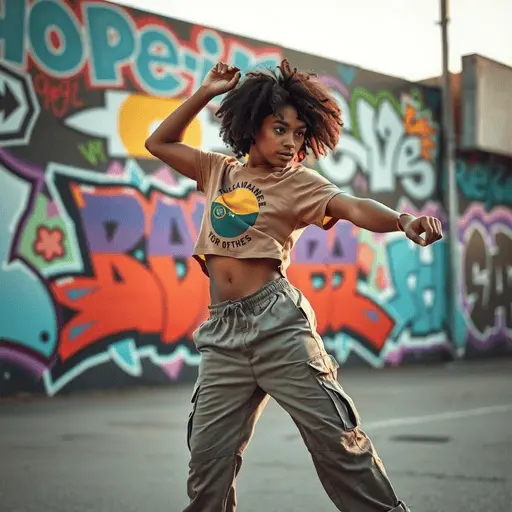
Juggernaut Flux Base
Prompt: A Brazilian street dancer with caramel skin and curly hair wearing a cropped graphic tee and loose cargo pants mid-movement in an expressive hip-hop pose, a vibrant graffiti-covered wall behind them. Golden hour lighting.
Num inference steps: 33
Seed: 42
Stay Connected with DeepInfra
Do not forget to follow us on Linkedin and on X (formerly Twitter).
 How to deploy Databricks Dolly v2 12b, instruction tuned casual language model.Databricks Dolly is instruction tuned 12 billion parameter casual language model based on EleutherAI's pythia-12b.
It was pretrained on The Pile, GPT-J's pretraining corpus.
[databricks-dolly-15k](http...
 Best AI Inference Platforms for Speed & Cost in 2026<p>Your monitoring dashboard says the API is fast and your invoice says the same thing in different units. Somewhere between the two, cost per completed request disappears. This guide compares the best AI inference platform options for speed and cost on the same footing: measured latency, measured throughput, current prices, and the math that turns […]</p>
 GLM-5.3-Flash API Providers: Speed & Cost<p>API Review Summary Metric Value Intelligence (Artificial Analysis Intelligence Index) 42 — well above the open-weight median (18) Speed 55.9 output tokens/sec — slower than the median (85.7 t/s) Latency (TTFT) 3.14s — higher than the median (2.05s) Cost (Z.ai first-party API) $0.15 / 1M input, $0.50 / 1M output; cache discount ~83% Cost efficiency […]</p>


© 2026 DeepInfra. All rights reserved.